Randomness determines which outcome occurs; variance measures how widely the possible outcomes are spread around their expected value. A fair die can produce an unlikely streak, and two games with identical average returns can expose players to very different swings. Neither randomness nor variance tells anyone what the next independent result will be.
That distinction matters in board games, video games, card games and games involving money. A designer uses probability to balance dice rolls, loot drops and critical hits. A player assessing a gambling game needs the payout distribution, return to player (RTP), house edge and volatility to understand what the mathematics actually permits.
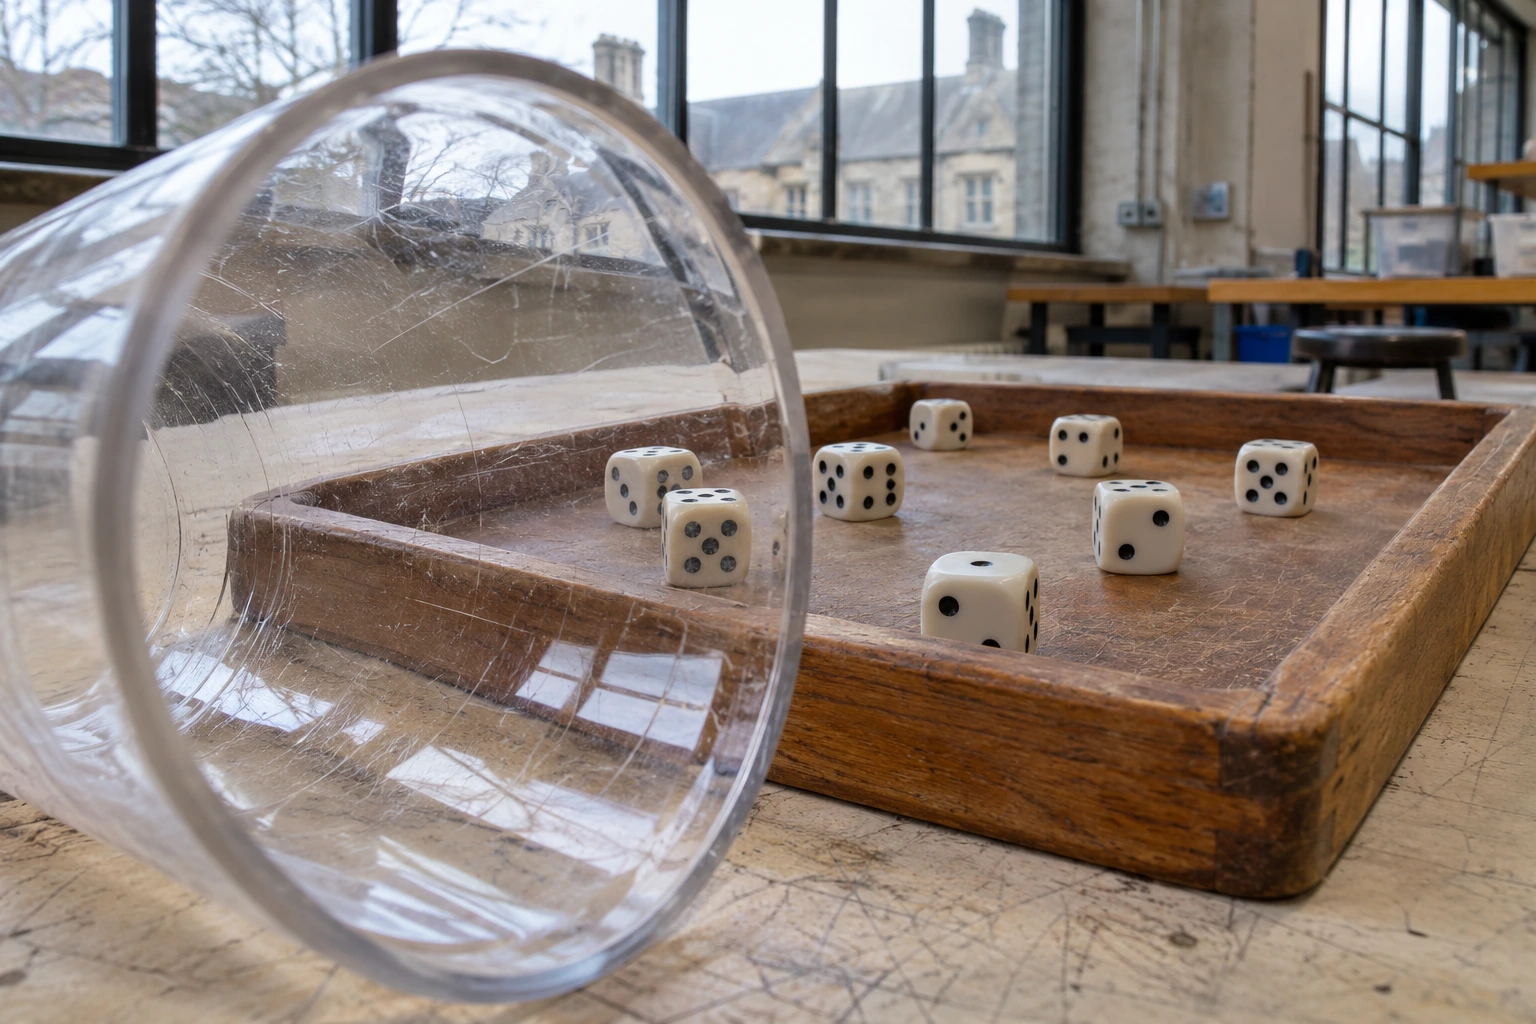
Randomness describes the selection of outcomes
A random process assigns probabilities to a set of possible results. The sample space contains those results; the probability distribution describes their likelihood. Each probability lies between zero and one, and the probabilities of mutually exclusive, exhaustive outcomes add up to one.
A fair six-sided die has a uniform distribution: each face has probability 1/6. The total of two fair dice does not have a uniform distribution. There are six ways to roll a seven but only one way to roll a two, giving probabilities of 6/36 (16.7%) and 1/36 (2.8%) respectively. Both dice can be perfectly fair while the distribution of their sum is uneven.
Randomness also needs a rule about independence. Consecutive rolls of an ordinary fair die are modelled as independent: earlier faces give no information about the next face. Cards drawn from a shuffled deck without replacement behave differently. After removing a non-ace from a standard 52-card deck, the probability that the next card is an ace becomes 4/51 rather than 4/52. Once an ace has been removed, it is 3/51. The deck is randomly shuffled, but successive draws are dependent.
Computer games introduce a further distinction. A pseudorandom number generator (PRNG) uses an algorithm and an initial seed to produce a sequence that behaves randomly for its intended purpose. The game then maps generated values to outcomes such as reel symbols, a loot item or a critical hit. A uniform source of random numbers can legitimately feed a non-uniform outcome distribution when the rules specify unequal probabilities. The integrity of the generator and the accuracy of that mapping are separate questions.
Variance measures the spread, not the direction, of results
In statistics, an outcome expressed as a number is a random variable, usually written as X. Its expected value, or mean, is the probability-weighted average of its possible results. The mean is not a prediction for any single event. A fair die has an expected roll of 3.5 even though 3.5 cannot appear on a face.
Expected value: E[X] = Σ pixi.
Population variance: Var(X) = Σ pi(xi − μ)2 = E[X2] − μ2, where μ = E[X].
Standard deviation: σ = √Var(X).
Variance gives greater weight to outcomes far from the mean because the deviations are squared. Its units are also squared: variance calculated from pound payouts is measured in pounds squared. Standard deviation takes the square root, bringing the measure back to pounds. A higher standard deviation indicates greater dispersion, not a better expected return or a guaranteed larger win.
Variance is always non-negative. It is zero only when the outcome is constant with probability one. A finite game with bounded numerical outcomes has finite variance, but a small number of unusual results can account for much of it. Unpredictability alone does not fix the amount of dispersion.
Two games with the same RTP and very different variance
Consider two invented games. Each round costs £1, and each result is independent of the previous round. The amounts below are gross payouts, including any stake returned, rather than profit. They are mathematical examples, not reported figures for a commercial game.
| Measure | Game A: smaller awards | Game B: rarer large awards |
|---|---|---|
| Possible gross payout | £0 or £1.80 | £0 or £9 |
| Probability of paying more than zero | 50% | 10% |
| Probability of paying zero | 50% | 90% |
| Expected gross payout | £0.90 | £0.90 |
| Theoretical RTP | 90% | 90% |
| Variance of gross payout | 0.81 £² | 7.29 £² |
| Standard deviation | £0.90 | £2.70 |
Game A's expected gross payout is (0.50 × £1.80) + (0.50 × £0) = £0.90. Its variance is (0.50 × 1.80²) − 0.90² = 0.81. Game B's expected gross payout is (0.10 × £9) + (0.90 × £0) = £0.90; its variance is (0.10 × 9²) − 0.90² = 7.29. The second payout distribution has nine times the variance and three times the standard deviation.
At a fixed £1 stake, both games have an expected net result of −£0.10 per round: a theoretical 10% house edge. Subtracting the constant stake from each payout changes the mean but does not change variance. The two games have equal average cost per round in the model, while their short-run experiences differ sharply.
Game B can produce extended sequences without an award. The chance of ten consecutive zero-payout rounds in a particular ten-round block is 0.910, or about 34.9%. A run of ten misses does not increase the next round's 10% chance of a payout. For Game A, ten zero-payout rounds in a specified block have probability 0.510, about 0.098%.
Why short sessions can disagree with the expected return
The law of large numbers concerns the average result of many trials under suitable assumptions. It does not require an individual player to reach the theoretical RTP by the end of a session, and it does not force a losing game to compensate for previous losses.
Across 100 independent £1 rounds in either hypothetical game, the expected total gross payout is £90 and the expected net result is −£10. The standard deviation of the total payout is approximately £9 for Game A and £27 for Game B. These figures come from σtotal = √n × σround when rounds are independent and identically distributed. They are measures of spread, not minimum or maximum losses. In Game B, the number of positive-payout rounds across 100 independent attempts follows a binomial distribution with parameters n = 100 and p = 0.10; its expected count is ten, not a guaranteed ten.
For independent rounds, the standard deviation of the average payout decreases as σ/√n. That can make an observed percentage look steadier over larger samples, while the absolute money at risk across all rounds still grows. Increasing the number of plays does not improve a negative expected value. With a constant house edge, more turnover increases the expected total loss.
The central limit theorem helps approximate distributions of totals or averages when its conditions are met and the sample is sufficiently large. It cannot turn a low-probability jackpot into a scheduled payment, and rare events can require enormous samples for a return estimate to stabilise. A session report without its number of rounds, stake sizes and payout distribution is not enough to infer a game's true volatility.
Variance, volatility, hit frequency and RTP are different measurements
The terms overlap in everyday discussion, especially around electronic gaming machines and slots, but each answers a different question.
RTP (return to player) The theoretical gross payout as a proportion of total stakes over repeated play under a specified game configuration. A 96% RTP corresponds to an expected gross return of £0.96 per £1 staked, not a promise to recover 96 cents in any particular round or session. House edge The expected share of a stake retained by the house in a conventional house-banked model. With no additional costs and RTP expressed on the same basis, house edge = 100% − RTP. A 96% RTP corresponds to a 4% theoretical edge. Variance and standard deviation Numerical measures of how dispersed payouts or net results are around their expected value. They require a distribution, not merely an RTP percentage. Volatility A practical description of payout variability. Labels such as low, medium and high volatility are not a universal measurement scale. A provider's volatility index also needs its definition before comparisons are valid. Hit frequency The proportion of rounds that trigger a defined payout or event. A hit might return less than the stake; it need not be a profitable win. The definition of a hit must be checked before comparing figures. Maximum win and jackpot The upper payout stated under specified game rules, or a prize that can grow in a progressive jackpot system. Neither figure reveals how likely the top prize is. Rare high-value awards can dominate theoretical RTP and substantially increase variance.A paytable and the probabilities attached to each outcome reveal more than any single marketing label. Bonus rounds, free spins, multipliers, wild symbols and progressive contributions all affect the complete payout model. The same game name may also appear with different RTP configurations. A fair comparison uses the exact version, stake basis and definitions.
Randomness in dice, cards, strategy and video games
The same mathematics works when the random variable is damage, score, resources or the number of turns to reach a goal rather than cash.
Dice pools and board-game decisions
One d6 produces six equally likely values. Rolling 2d6 and adding them produces an exact triangular distribution centred on seven. A seven occurs in 16.7% of throws, while a two or twelve occurs in 2.8% each. Game designers can use this concentration to make middle results common and extremes uncommon. A d20 skill check, by contrast, spreads twenty faces uniformly before modifiers and any advantage or reroll rules are applied.
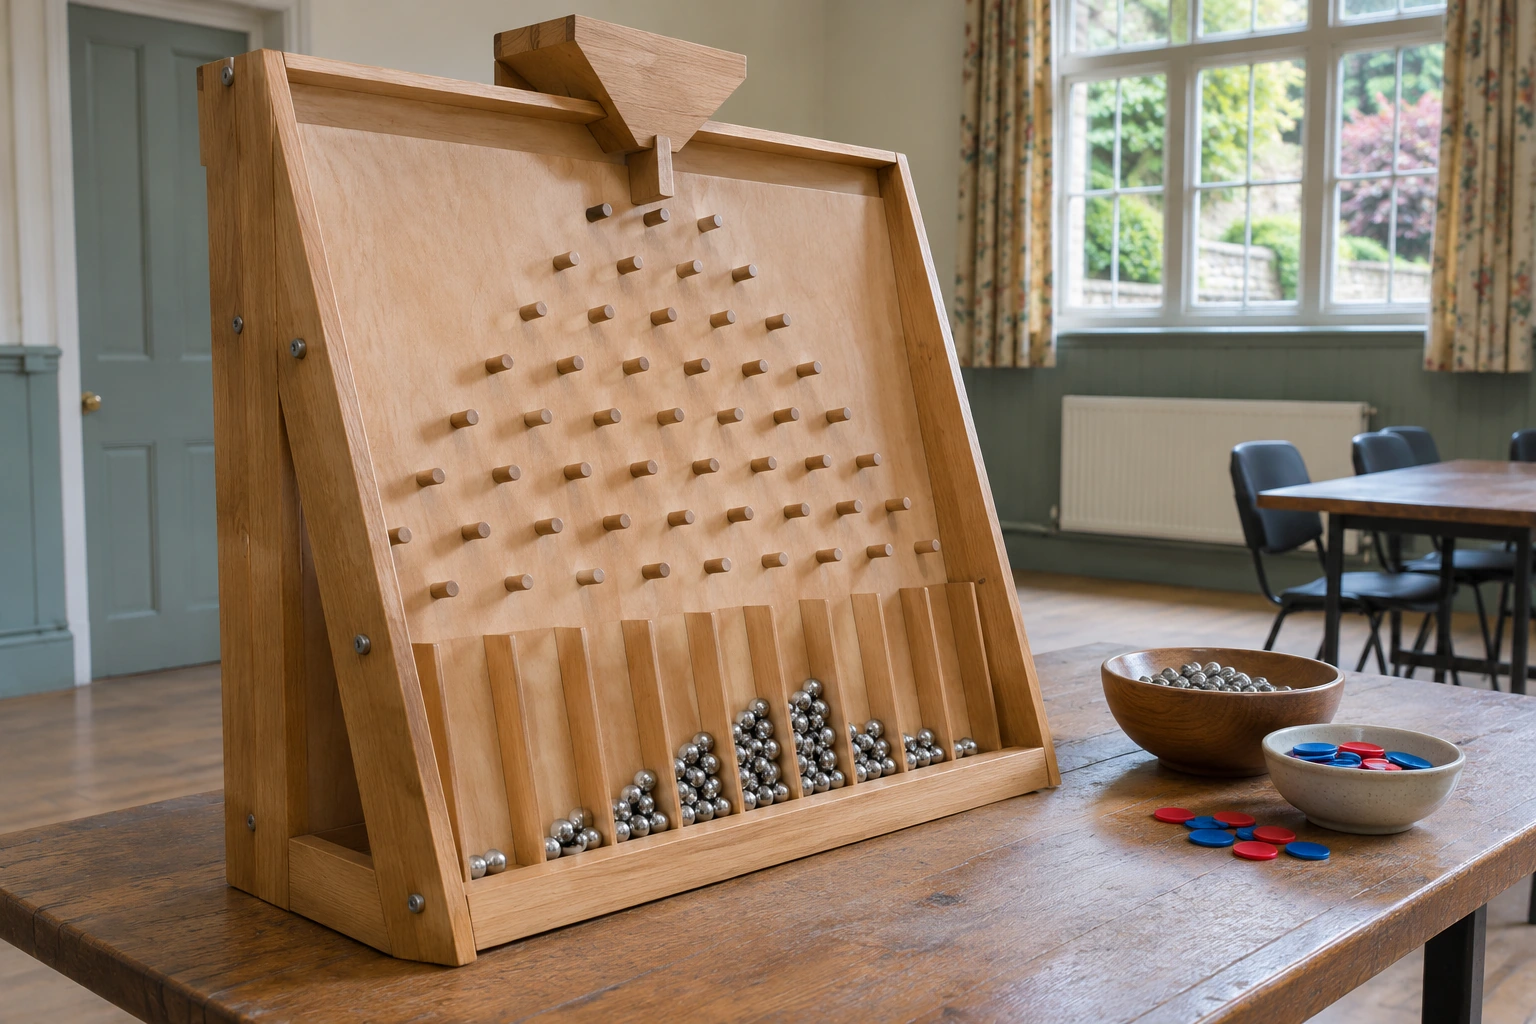
Rerolls, exploding dice, critical hits and dice pools change the outcome distribution. Comparing their averages alone can hide the frequency of catastrophic failures or exceptional successes. Risk-sensitive decisions may favour a steadier option even when its expected score is slightly lower.
Shuffled decks and changing game states
Card counting, drafting and deck-building games involve conditional probability. Every draw changes the remaining sample space when cards are not replaced. The correct variance of a total may include covariance between draws; the simple square-root-of-n rule for identical independent rounds is not automatically valid.
Loot drops, critical hits and player agency
Video games can use weighted loot tables or a disclosed guarantee after repeated attempts; those rules mean outcomes need not be identically distributed. Regulated gambling outcomes are different: Gambling Commission RTS 7 prohibits adaptive or compensated behaviour in the games to which it applies.
Skill matters through the decisions a player controls: choosing an attack, managing resources, adjusting a strategy or responding to a revealed roll. Randomness can enter before a decision, leaving room to adapt, or after it, making the immediate result uncertain. An individual result may be luck-driven while better decisions improve expected performance across many situations.
Streaks, near misses and the gambler's fallacy
A streak is not evidence that an independent random process has developed a memory. Five heads in five pre-specified fair coin tosses have probability (1/2)5 = 1/32, or 3.125%. After those five heads, the probability of heads on the next fair toss remains 50%. The probability of seeing some five-head run somewhere in a long sequence is greater than the probability for one fixed five-toss block.
The gambler's fallacy treats a result as “due” after a run of opposite outcomes. The hot-hand belief can make a winning streak feel predictive even when rounds are independent. Neither impression changes the probabilities. A visually close miss also does not establish that a win was nearly secured; its meaning depends on how game results and animations are generated.
The independence assumption does not cover card draws without replacement, state-dependent bonus features or explicitly designed pity systems, which can change conditional odds. Independence must come from the rules and mechanism, not from the word “random” alone.
How randomness and fairness can be checked
Randomness testing asks whether an output sequence behaves consistently with a specified model. Fairness additionally asks whether the model, game rules, probability mapping and payouts match what the participant has been told. A random generator does not make an unfavourable bet mathematically profitable.
- Distribution: Are outcomes produced with the intended probabilities? A generator can supply uniform numbers while a game deliberately maps them to weighted results.
- Independence: Do results reveal an unintended relationship across draws? Serial-correlation and runs tests can detect certain departures from a claimed model.
- Unpredictability: Is it computationally infeasible to forecast the next value without secret internal state or seed information? Looking statistically random is not enough to establish security.
- Implementation: Do shuffling, scaling, reel mapping, bonus logic and payout tables preserve the specified probabilities?
- Verification: Is there independent technical testing, a clear rule set, a stated RTP for the actual game configuration and an auditable process for changes?
Statistical techniques can include chi-square distribution checks, runs tests and serial-correlation tests. They provide evidence within their assumptions and sample limits; passing a suite does not prove absolute randomness or rule out every implementation flaw. The US National Institute of Standards and Technology's SP 800-22 distinguishes statistical testing from the security analysis needed to assess a generator.
A player's short record of wins and losses cannot establish that an RNG is defective or that a stated theoretical RTP is false. Rare payouts, differing stakes and incomplete observations make that inference especially unreliable. A Monte Carlo simulation can estimate expected results, payout quantiles and variance when the underlying rules are available. Confidence intervals describe uncertainty in those estimates, not guaranteed boundaries for individual sessions. Reproducing a probability model requires the actual game rules and distribution; observations alone are subject to sampling error.
Game randomness and fair play in Great Britain
In Great Britain, check the operator against the Gambling Commission public register and read the specific game rules. Published return figures, payout schedules, jackpot eligibility and player controls can differ between games and versions. A mathematical model or laboratory test does not establish that an operator is licensed.
Mathematical probabilities and expected returns cannot predict an individual session or eliminate the risk of losing money.
A practical way to assess a game's mathematical risk
Start with the actual outcome model. Identify the random variable: gross payout per £1 staked, net profit per round, damage per attack or points per turn. Record whether outcomes are independent, conditional on game state, or drawn without replacement.
Separate the average from the spread. Calculate expected value from outcomes and their probabilities. Use variance and standard deviation to describe the dispersion. For monetary games, distinguish theoretical return from the chance of finishing a session ahead. The latter requires the distribution and a specified number of rounds, not RTP alone.
Check the tails, not only the label. Compare the probability of receiving nothing, the size and frequency of awards, maximum payouts, bonus-feature conditions and any unreported rare events. Two distributions can share a mean and standard deviation but differ in the likelihood of extreme outcomes. A low, medium or high volatility label cannot replace those probabilities.
Keep the stake and time horizon fixed. If every payout scales proportionally with stake, doubling the stake doubles expected monetary payouts and standard deviation while multiplying monetary variance by four. Changing stakes, bonus rules or the number of rounds prevents a clean like-for-like comparison. A finite bankroll also creates a risk of ruin: funds may be exhausted before a rare high payout occurs. Calculating that risk requires more than RTP. A loss limit concerns cash exposure; it is not a method for improving the odds.
Check what can actually be verified. Stated rules, the applicable RTP configuration and independent assessments provide stronger evidence than anecdotes about lucky or unlucky sessions. Where the full payout distribution is unavailable, an exact volatility figure or session-level probability cannot be calculated reliably from a marketing description.
Common questions about variance and randomness
Does a higher RTP mean a game is less volatile?
No. RTP describes the expected mean payout, while volatility describes its spread. Two games can share the same RTP and have very different variance, as the £1 examples demonstrate.
Can a sequence of losses make a win more likely?
Not when rounds are independent and their probabilities remain unchanged. A changing deck composition or an explicitly state-dependent feature is a different probability model.
Is high variance the same as a high chance of winning big?
No. High variance indicates greater squared dispersion around the mean. It does not, by itself, provide the probability of any particular prize, the hit frequency or the likelihood of a profitable session.
Can a player reduce variance?
Smaller proportional stakes reduce monetary swings without changing a game's underlying return or probabilities. In games with strategic choices, selecting a lower-risk action can change the distribution of outcomes. Neither approach turns a negative-expectation gambling game into a positive one.
Is a game fair just because its RNG is random?
No. An RNG can be unpredictable while the game still has a house edge. Fair implementation concerns the claimed probabilities, payout rules, mapping, transparency and applicable technical standards, not simply the presence of random numbers.
Is a losing streak proof that an RNG is rigged?
No. Independent events naturally produce runs and clusters. Identifying a defect requires evidence about the expected distribution, a sufficient data set and the implementation itself; a handful of outcomes is not a reliable test.